Dievio
Most agency lead list problems are not data problems. They are handoff problems. A researcher builds a search that looks right, someone eyeballs the count, an export gets pulled, and a CSV lands in a client's inbox three days later with duplicate rows, a title column that reads "Owner" for people who left the company last quarter, and no explanation of what was filtered out. The client runs one campaign, gets a mediocre reply rate, and starts asking whether the list was any good.
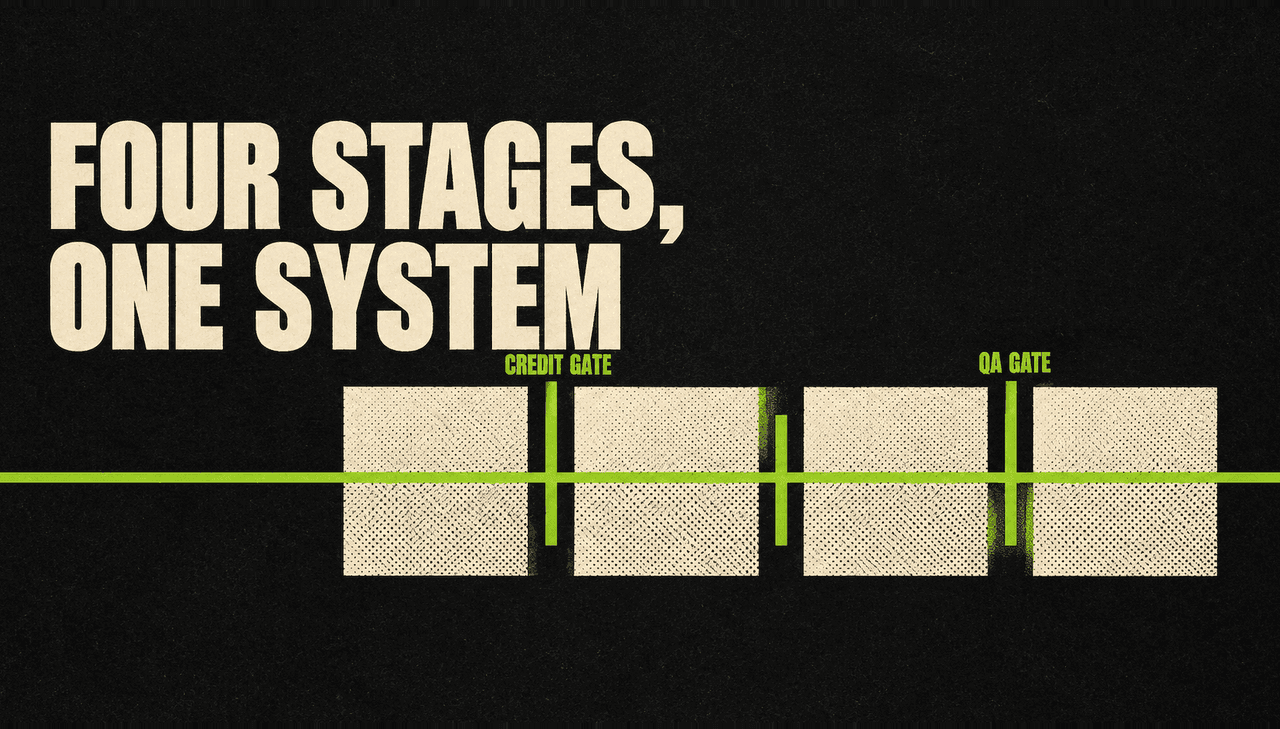
The fix is not a better researcher. It is a workflow. Agencies that deliver lead lists reliably at scale treat search, preview, export, and delivery as four connected stages with defined inputs, defined outputs, and a gate between each one. This article maps that workflow end to end, including where automation should replace a manual handoff, where a human still needs to look at the data, and how to keep credit spend predictable across a dozen client accounts at once.
Why workflow automation matters for agency lead lists
An ad-hoc lead list process works fine for the first client. It starts breaking at the third. The failure is rarely dramatic — it shows up as a researcher spending an afternoon rebuilding a search they already built two months ago, or a delivery going out with a segment that overlaps last month's export by 40%, or a credit balance getting drained on a filter combination that returned nothing useful.
Prospecting is a repeatable motion, not a creative one. The core prospecting workflow is essentially the same every time: define who you are looking for, confirm they exist in usable volume, pull the records, and put them somewhere the client can act on them. When that motion is standardized, three things improve at once.
- Throughput. A repeatable workflow means a new client account can be onboarded into an existing template instead of a blank page.
- Quality. Every delivery passes the same checks, so a bad segment gets caught before it reaches the client rather than after a campaign underperforms.
- Margin. Credits are the variable cost in agency list building. Gating them behind a preview step is the single highest-leverage change most agencies can make.
The four stages below are the operating system. Everything else — templates, naming conventions, credit budgets, reporting — hangs off them.
Stage 1: ICP definition and search query design
Search quality determines everything downstream. If the filter combination is wrong, no amount of QA at the export stage will save the delivery, because you will be validating the wrong population. This is why the workflow starts with a written ICP rather than a search interface.
An ICP that is usable for list building has to be expressed in dimensions a search engine can actually filter on. "Mid-market SaaS companies that care about data quality" is not a filter. "B2B SaaS companies, 100–1,000 employees, headquartered in the US or UK, with a VP Sales or Head of Sales title" is.
| ICP dimension | Search filter translation | Common failure |
|---|---|---|
| Company size | Employee range or revenue band | Using headcount when the client buys on revenue, or vice versa |
| Industry | Industry / sector taxonomy, plus keyword fallback | Relying on a single industry label that misses adjacent categories |
| Geography | Country, region, or metro | Filtering by HQ location when the buying team is distributed |
| Role | Job title includes / excludes | Title matching that catches "Assistant to the VP of Sales" |
| Seniority | Seniority band (C-level, VP, Director, Manager) | Assuming seniority labels are consistent across all records |
| Technology or signal | Tech stack, funding, hiring, or growth filters | Stacking too many signals until the segment collapses to zero |
Two disciplines matter here. First, define the exclusion list as carefully as the inclusion list — competitor domains, current customers, agencies, and staffing firms are the usual noise. Second, write the search down. A search that lives only in someone's browser history cannot be handed off, audited, or repeated next month.
If the client's ICP is vague or internally contested, resolve that before building anything. A structured client ICP validation workflow is the upstream input to everything in this article; running searches against an unvalidated ICP is how agencies end up rebuilding the same list three times. For broader context on how B2B lead generation strategy maps to targeting decisions, Salesforce's guide to B2B lead generation is a reasonable reference for framing the targeting conversation with clients.
Stage 2: Preview before export
Preview is the cheapest quality gate in the entire workflow, and it is the one agencies skip most often. Previewing means running the search and looking at the count — and a sample of the records — before committing credits to a full export.
Preview answers four questions that should be answered before any export happens:
- Does this segment exist at the volume the client expects? A client who asked for 2,000 contacts and gets 180 needs to know that before the delivery, not after.
- Did a filter silently break the search? A single over-restrictive filter can take a healthy segment to near zero. Preview surfaces that in seconds instead of after a wasted export.
- Is the title mix right? If the client wants decision-makers and the sample is full of coordinators, the filter needs adjusting, not the client's expectations.
- Is the segment overlapping a previous delivery? Preview plus a dedupe check against prior exports prevents the same contacts being sold twice.
It helps to define volume bands per client up front. A practical convention: under 200 records is too thin to be a standalone delivery, 200–1,500 is a normal monthly batch, and anything above 5,000 should be split into sub-segments by role or region so the client's outbound team can sequence them differently. You can preview lead counts before exporting to validate segment size and coverage before spending anything.
The output of this stage is a decision: export as-is, adjust filters, or go back to the client with a revised volume expectation. That decision should be recorded, because it is the first thing you will want to reference when the client asks why the delivery was smaller than the estimate.
Stage 3: Export automation
Export is where credits get spent, which makes it the stage that needs the tightest controls. It is also the stage where manual work creates the most inconsistency, because two researchers pulling the same search will produce two different CSVs with different columns, different ordering, and different dedupe treatment.
Standardize four things:
- Format. One canonical export format per client — usually CSV for outbound tools, or a CRM-ready field mapping if the list is going straight into the client's system. Decide once, document it, and never improvise.
- Field selection. Include only fields the client will actually use. Extra columns create confusion and, in some tools, import errors. Typical minimum: first name, last name, title, company, company domain, email, LinkedIn URL, location.
- Dedupe logic. Dedupe within the export by email and by company-plus-name, then dedupe against all prior deliveries for that client. Cross-delivery dedupe is the one agencies forget, and it is the one clients notice.
- Credit gating. Never let an export run without a preview-confirmed count and an approved credit budget for that client. If the export would exceed the monthly budget, it stops and escalates.
For one-off pulls, the UI is fine — build the search with the filters you need, confirm the count, export. For anything recurring, the manual pull becomes a liability, because it depends on a person remembering to run it and applying the same settings. The search interface itself supports lead search with 20+ filters, which is enough to express most client ICPs without workarounds.
The output of this stage is a raw export plus an export log: search definition, filters applied, record count, credits consumed, and timestamp. That log is what makes the next stage auditable.
Stage 4: Client delivery
Delivery is a packaging problem, not a data problem. The same list can feel professional or sloppy depending entirely on how it arrives. Three decisions define the delivery format.
Channel. Email attachment works for small, occasional deliveries. A shared drive or client portal works better for recurring batches, because it creates a version history the client can reference. A direct CRM push is best when the client's outbound team lives in the CRM and will never open a CSV — but it requires field mapping and a test import before the first real delivery.
Naming convention. Adopt one and never deviate. A workable pattern:
client-slug_segment_YYYY-MM-DD_v1.csv
For example, acme-saas_vp-sales-us_2025-03-01_v1.csv. The version suffix matters more than it seems — when a client asks for a correction, you ship v2 and the history stays legible.
Client-facing summary. Every delivery should arrive with a short note covering what was searched, how many records were delivered, what was excluded and why, and what the client should do next. This is the difference between a vendor and a partner. It also preempts the most common client objection, which is "why is this smaller than I expected?"
Match the delivery format to how the client will actually use the list. If the client's SDR team loads lists into an outbound sequencer, deliver a sequencer-ready CSV with the exact columns that tool expects. If the client's marketing team runs the list through a CRM, deliver a mapped import file. Format friction at the delivery stage shows up as "the list didn't work," even when the data was fine.
Automation handoffs between stages
The value of mapping the workflow is that each stage has a clear trigger, output, and owner. When a handoff is undefined, it becomes a Slack message that nobody owns.
| Stage | Trigger | Output | Owner | Next-stage input |
|---|---|---|---|---|
| ICP & search design | New client onboarding or ICP revision | Written search spec with filters and exclusions | Strategist / account lead | Search spec |
| Preview | Search spec approved | Count, sample rows, volume decision | Researcher | Approved segment + expected volume |
| Export | Preview approved and credits budgeted | Raw export + export log | Researcher / automated job | Raw file + log |
| QA | Export complete | Pass/fail with flagged rows | QA reviewer (not the exporter) | Cleaned file |
| Delivery | QA passed | Client-ready file + summary note | Account lead | Client feedback, next cycle |
Two of these handoffs are worth automating first. The preview-to-export handoff is the easiest win: if the preview count meets the agreed threshold, the export can be triggered without a human decision, with the credit budget as the guardrail. The export-to-QA handoff is the second: automated checks for duplicates, missing emails, and malformed domains can run before a human ever opens the file, so the reviewer spends their time on judgment calls rather than mechanical scanning.
Keep humans in the loop at two points regardless of how much you automate: the ICP-to-search translation, and the final QA pass. Those are the two places where a wrong decision is expensive and hard to detect downstream.
QA gates and approval checkpoints
QA is not a vibe check. It is a fixed list of checks that runs before any client-facing export leaves the building. Lead scoring frameworks are useful here as a mental model — lead scoring is fundamentally about defining what "good" means before you evaluate records, and the same discipline applies to list QA.
A practical pre-delivery checklist:
- Sample row review. Open ten random rows and read them. Do the titles make sense for the segment? Are the companies real and in the right industry?
- Email validity spot-check. Confirm the export contains only records with deliverable emails, and check the invalid or missing rate against the client's tolerance.
- Title and seniority accuracy. Verify that the seniority filter did not leak junior titles, and that title matching did not catch adjacent roles.
- Duplicate scan. Within the file, and against all prior deliveries for that client.
- Segment size sanity check. Compare the delivered count to the preview count. A large gap means something changed between preview and export.
- Exclusion verification. Confirm competitors, current customers, and internal domains were actually excluded.
- Field completeness. Check that required columns are populated at an acceptable rate, not just present.
The reviewer should not be the person who built the export. Self-review catches almost nothing, because the person who built the search already believes it is correct. A second pair of eyes on a fixed checklist catches the errors that matter.
Recurring delivery patterns
Once a client has received one good list, the conversation shifts to cadence. Three models cover most agency engagements, and the right one depends on the client's buying cycle and how fast their target market changes.
| Model | Best for | Typical volume | Main risk |
|---|---|---|---|
| Weekly refresh | High-velocity SDR teams, fast-moving markets, short sales cycles | 100–400 new contacts per week | Segment exhaustion — the same ICP runs dry |
| Monthly batch | Most agency retainers, mid-market and enterprise targets | 500–2,000 per month | Stale titles if the list sits unused for weeks |
| Campaign-triggered | Clients running discrete campaigns, launches, or event follow-up | Varies by campaign | Unpredictable credit spend and scheduling |
Monthly is the default for a reason: it matches most B2B buying cycles, it is easy to budget credits against, and it gives the client enough time to actually work the previous batch. Weekly only makes sense when the client has the outbound capacity to consume the volume — delivering 400 contacts a week to a two-person SDR team just creates a backlog and a false sense of progress.
Whatever the cadence, the workflow should be identical each cycle. The search spec stays fixed unless the ICP changes, the preview gate stays in place, the QA checklist runs, and the delivery format stays consistent. A recurring lead list delivery workflow that varies month to month is not a workflow — it is a series of one-offs with a retainer attached.
UI vs API workflows for agencies
Not every agency needs an API, and buying one too early adds operational overhead without much payoff. The decision comes down to volume, repetition, and how many client accounts you are running through the same process.
| Factor | UI workflow | API workflow |
|---|---|---|
| Best fit | One-off lists, exploratory searches, small client counts | Multi-client recurring delivery, white-label products |
| Setup effort | None | Initial engineering time, then near-zero per run |
| Consistency | Depends on the operator repeating steps correctly | Identical output every run by definition |
| Credit visibility | Visible in the interface at the point of export | Requires logging and monitoring to stay visible |
| Audit trail | Manual export logs | Automatic, timestamped, queryable |
| Scaling ceiling | Limited by researcher hours | Limited by credit budget and rate limits |
The practical threshold: once you are running the same search pattern for more than three or four clients on a recurring schedule, the API starts paying for itself in consistency alone. The bigger benefit is that a lead generation API for recurring workflows lets you schedule runs, log credit consumption per client, and push results directly into a client's CRM or a shared drive without a human in the middle.
One caution: API workflows make credit overruns easier, not harder, because nothing stops a misconfigured job from running repeatedly. Build a hard credit ceiling per client into the job itself, and alert when a run exceeds its expected record count.
Common failure modes and how to fix them
Almost every agency list problem traces back to a specific stage where a gate was missing. Here are the ones that show up most often.
| Failure | Where it should have been caught | Fix |
|---|---|---|
| Empty or near-empty segment | Preview | Test filters individually; relax the most restrictive one first |
| Duplicate rows across deliveries | Export | Dedupe against all prior client exports, not just the current file |
| Credit overrun mid-month | Export | Hard credit ceiling per client, enforced before the export runs |
| Client expected more contacts than delivered | Preview | Confirm volume expectations in writing before the first export |
| Stale titles and departed contacts | QA | Spot-check titles; refresh lists older than 60–90 days before reuse |
| Wrong seniority mix | Search design | Add explicit title exclusions; review sample rows at preview |
| List delivered in a format the client can't import | Delivery | Confirm the destination tool and its required columns during onboarding |
Notice the pattern: most failures are caught by a gate that already exists in the workflow. The problem is rarely that the gate is wrong — it is that the gate was skipped because the delivery was urgent. That is exactly when the workflow needs to be non-negotiable.
Connecting the workflow to client reporting and ROI
A standardized workflow produces something beyond clean lists: it produces the data you need to have a renewal conversation. If every delivery is logged with the search definition, record count, credits consumed, and delivery date, you can report on list volume over time, cost per delivered contact, and how quickly the client's outbound team worked through each batch.
Those numbers matter because they shift the conversation from "did you send us a list?" to "here is what the list produced." If the client's reply rate is low, you can check whether the segment was too broad, whether titles were off, or whether the list sat unused for three weeks before the first send. If the reply rate is strong, you have a case for expanding the segment or increasing cadence.
Without the log, every renewal conversation restarts from zero. With it, you are reviewing a shared dataset.
Standardizing the workflow across clients
The final step is turning the workflow into a template that new clients inherit rather than a process each account lead reinvents. That means four artifacts, maintained centrally:
- A search spec template that captures ICP dimensions, filters, exclusions, and expected volume in one document.
- A QA checklist that is identical for every client, with client-specific additions where needed.
- A naming and delivery convention that every account uses without exception.
- A credit budget per client, tracked against actual consumption, so margin is visible before the month closes.
Onboarding a new client then becomes an exercise in filling in a template rather than designing a process. The first delivery still takes real work — the ICP translation is never trivial — but the second, third, and twelfth deliveries run on rails.
That is the whole point of connecting search, preview, export, and delivery into one system. It is not about removing people from the process. It is about making sure the people you have are spending their time on judgment — segment design, QA, client communication — instead of rebuilding the same search for the fourth time this quarter.
If you are running list delivery across multiple client accounts and want a workflow that holds up at that scale, start with the agency lead lists setup and build the four stages around it. The gates are what make the volume sustainable.