Dievio
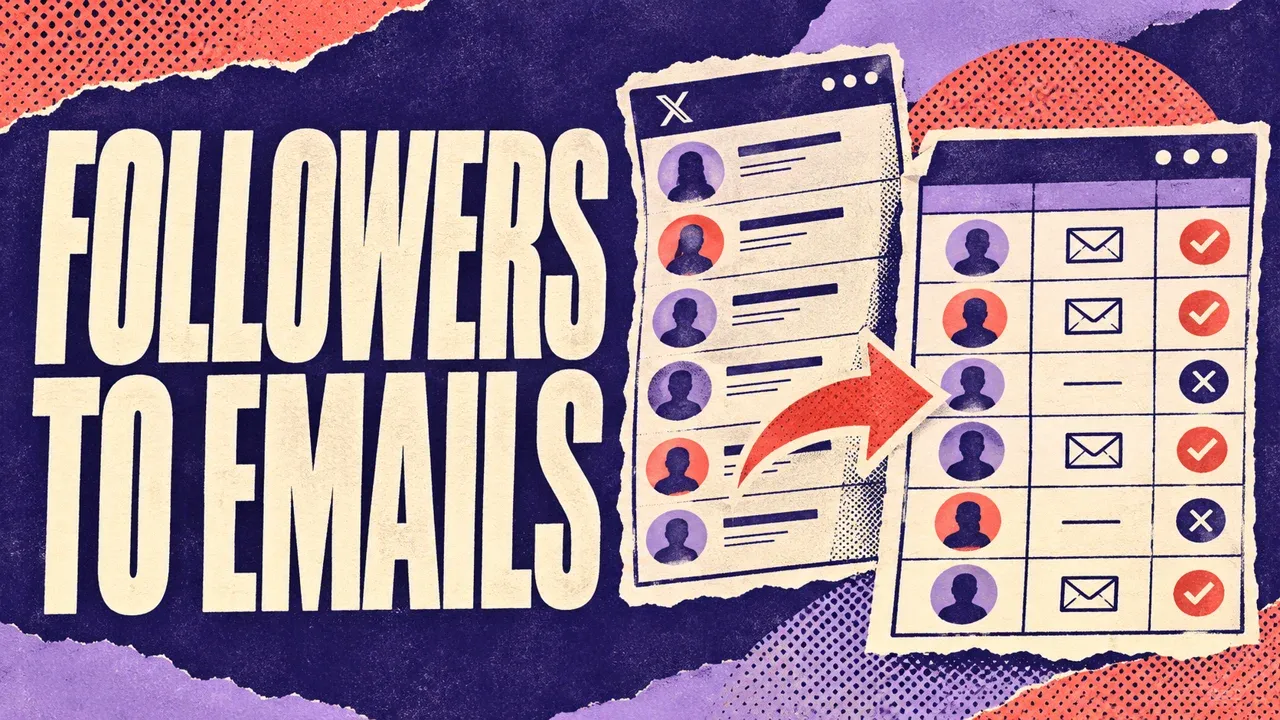
To find emails for a Twitter followers list, use the Twitter Followers Scraper to collect usernames, then pass those usernames to the Twitter Email Scraper. Match the returned screenname values back to the follower list to build an enriched CSV.
This guide focuses on keeping the whole audience file intact: who follows which target, which handles were submitted for lookup, and which received a match. If you want a first-run tour of both input forms, start with the Twitter email finder walkthrough.
Why you need two Actors and two kinds of files
The follower Actor collects connections around a public target. The email Actor looks up available records associated with submitted usernames. It does not collect the audience for you, and an email match is not guaranteed for every follower.
| File | What it preserves |
|---|---|
| Original follower CSV | Every target-to-follower relationship. |
| Unique submitted usernames | The exact handles sent for email lookup. |
| Email results | The available matches returned by the second Actor. |
| Enriched follower CSV | Each original relationship with its match and lookup status. |
A person can follow several target accounts. Look up that username once and reuse the result across those source rows. Keeping the master audience file separate avoids losing useful attribution while removing duplicate lookup work.
Step 1. Collect followers as usernames
Open the Twitter Followers Scraper, click Try for free and open its Input form in Apify Console. Enter the public account whose followers you want. It can be a competitor, creator, company or another accessible public profile.
- Enter the target without a leading
@. - Enable followers and disable following for a follower-only audience.
- Set a collection limit large enough for your intended lookup list.
- Choose Usernames under Result Format. The default is numeric IDs.
- Review pricing and spending settings, then start the run.
- After completion, download the Dataset as CSV and read
SUMMARYfor failed jobs.
This paid-plan example requests up to 5,000 followers of nasa. Replace the target with your chosen public account.
{
  "userNameList": ["nasa"],
  "maxFollowers": 5000,
  "getFollowers": true,
  "getFollowing": false,
  "outputMode": "usernames"
}
Free-plan collection is capped at 1,000 total results per run. Paid plans support much larger per-target limits, up to 5,000,000 per direction. Count the actual distinct usable handles after export; the requested cap does not establish that you received enough for email lookup.
For the direction switches, output formats and multi-target setup, see the follower CSV guide and the current follower input reference.
Step 2. Prepare one lookup list while retaining audience rows
In a working copy of the follower file, keep rows with status=item, relation=followers and mode=usernames. Add a stable source_row column. The follower handle comes from value; query_value identifies the source target.
- Create a
lookup_keyby trimming the handle, removing one leading@and lowercasing it. - Keep the original columns and every relevant connection row.
- Copy lookup keys to another sheet and remove duplicates there.
- Exclude blank, malformed and unsupported numeric-ID inputs from the lookup list.
- Count the remaining distinct handles.
- Save the exact submitted handles as one username per line, without the column header.
For example, @DemoBlue and demoblue share one lookup key. If DemoBlue follows two target accounts, both relationships remain in your master file while the email Actor receives that handle once.
If fewer than 1,000 usable usernames remain, combine relevant public audiences or add another existing username list, then deduplicate again. A numeric-ID export needs verified username resolution or a new username-mode export before this email workflow.
Step 3. Run the email lookup
Open the Twitter Email Scraper and click Try for free to reach its Input form in Apify Console. Paste the complete prepared list into Usernames, one handle per line.
Set Max Results to leave room for the available matches. For 5,000 submitted handles, use 5,000 if you want room for a match for every handle. The output ceiling accepts 100–1,000,000; it is separate from the 1,000-username input minimum.
Review pricing and the run budget, then start the Actor. Save the completed Dataset as CSV with screenname and email. Keep the exact submitted list, run ID, Dataset ID, output cap and terminal run status with this batch.

The screenshot shows the read-only email input reference. Paste the full real list into the Console form. A short illustrative list does not meet the Actor’s minimum.
 Dievio
Your next customer starts here.
Find decision-makers by role, company and location. Build your next prospect list in Dievio.
Find my leadsFree audience preview · No credit card
Step 4. Join email matches back in a spreadsheet
Create an email-results sheet. Normalize its screenname column using the same rule as lookup_key. Use that key for an exact lookup from the original follower sheet into the results sheet.
- Keep the follower sheet as the master table.
- For each row, check whether its key was actually submitted.
- Find returned emails by normalized
screenname. - Attach a single unambiguous match, or flag multiple different addresses for review.
- Keep rows without matches and give them an explicit status.
- Confirm that the final master table has the same number of rows as the filtered source.
| Target audience | Username | Status | |
|---|---|---|---|
| sample_alpha | demoblue | Matched | alex@northstar.example |
| sample_beta | demoblue | Matched | alex@northstar.example |
| sample_alpha | demoamber | Submitted; no returned match | Empty |
| sample_alpha | demogray | Not submitted | Empty |
One distinct matched username fills two audience rows here. A missing match is different from a username that was never submitted. If the run failed or reached its cap, retain that batch status before interpreting its missing results.
Optional: reproduce the join from three local files
For a repeatable local merge, save followers.csv with your filtered audience rows, submitted.txt with the exact handles actually sent, and email-results.csv with screenname and email. Run the following with Python 3.10 or newer in that folder.
The script reads and writes local files. It preserves source rows, flags unsupported inputs and leaves multiple different email matches for review. It does not start another Actor run.
import csv
import re
from collections import defaultdict
from pathlib import Path

def key(value):
    handle = (value or "").strip().removeprefix("@").lower()
    return handle if re.fullmatch(r"[a-z0-9_]{1,15}", handle) else ""

submitted = {
    key(line) for line in Path("submitted.txt").read_text().splitlines()
} - {""}
matches = defaultdict(set)

with open("email-results.csv", newline="", encoding="utf-8-sig") as f:
    for row in csv.DictReader(f):
        handle = key(row["screenname"])
        email = (row.get("email") or "").strip()
        if handle in submitted and email:
            matches[handle].add(email)

with (
    open("followers.csv", newline="", encoding="utf-8-sig") as source,
    open("joined.csv", "w", newline="", encoding="utf-8") as output,
):
    reader = csv.DictReader(source)
    fields = [*(reader.fieldnames or []), "lookup_key", "match_status", "email"]
    writer = csv.DictWriter(output, fieldnames=fields)
    writer.writeheader()
    for row in reader:
        handle = key(row["value"]) if row["mode"] == "usernames" else ""
        emails = matches.get(handle, set())
        if not handle:
            status = "unsupported_input"
        elif handle not in submitted:
            status = "not_submitted"
        elif len(emails) > 1:
            status = "review_multiple_matches"
        elif emails:
            status = "matched"
        else:
            status = "no_returned_match"
        writer.writerow({
            **row, "lookup_key": handle, "match_status": status,
            "email": next(iter(emails)) if status == "matched" else "",
        })
Save joined.csv alongside the original files. no_returned_match describes the exported results for that submitted handle. Keep a separate batch record to distinguish a completed lookup from a capped or incomplete run.
Process large audiences without losing track of batches
The follower Actor supports large public audiences, while the email Actor supports bulk input and up to 1,000,000 returned records per run. For a million distinct handles, ten batches of 100,000 are one manageable approach. Keep each input file and its run IDs separate.
Every email batch must contain at least 1,000 usable handles. Redistribute a smaller final remainder into the preceding batches. Set max_results with the size of each batch in mind, and deduplicate across audiences before lookup.
Read every page when downloading a large Dataset through an API or agent. Keep completed batch output before retrying failed work. A new unmatched-only batch still has to meet the email Actor’s input minimum.
Review each Actor’s current Pricing tab and use approved event-charge caps. The follower Actor also has Apify platform usage charges, so include those in the project budget. A limit on returned records is another boundary on the work you are asking it to save.
Let your agent coordinate both Actors through Apify MCP
Connect an MCP-compatible agent to https://mcp.apify.com and authorize your Apify account using the Apify MCP guide. Give it the target accounts or existing CSV and the budget for each stage.
Build an enriched Twitter audience CSV.
Actors:
x_guru/twitter-follower-scraper
x_guru/twitter-email-scraper
Targets or existing file: [MY_INPUT]
Follower limit per target: [LIMIT]
Approved event-charge caps USD:
followers [AMOUNT], email [AMOUNT].

Inspect both current input schemas.
Collect followers with username output.
Keep every source relationship and add
a source_row key. Make a separate unique
list of valid normalized usernames.
If fewer than 1,000 remain, report the
count and wait for more input.

Submit complete email batches, each with
at least 1,000 handles. Set max_results
to allow the intended batch output.
Apply approved caps through
callOptions.maxTotalChargeUsd.
Retain every submitted list and run ID.

Wait for terminal statuses. Read SUMMARY
for followers and all result pages.
Join email screenname to follower value
using the same normalized key.
Preserve all original audience rows.
Flag multiple matches and incomplete
batches. Save the master audience CSV,
unique contacts and batch status report.
Report row counts, distinct handles,
matches, run IDs and Dataset IDs.
The agent starts Actors with call-actor, waits using get-actor-run and reads Datasets with get-dataset-items. It should keep the submitted list and batch status as carefully as the email output, because those explain your final coverage.
Check the counts before using the enriched list
Count original audience rows, distinct usable handles, submitted handles and distinct matched usernames separately. In the fictional table, four source rows represent three usernames; two usernames were submitted and one matched. That match fills two source rows.
Report both lookup coverage and audience coverage. Keep not-submitted, no-returned-match, multiple-match and incomplete-batch cases visible. Review unusual matches and check deliverability before using the addresses for outreach.
For the individual input forms, return to the Twitter email walkthrough or follower export guide. For repeated runs from your own application, follow the Apify run and Dataset export guide.