Dievio
Two endpoints, two jobs
Most teams that get frustrated with a B2B data API are not frustrated with the data. They are frustrated because they called the wrong endpoint. They sent a list of company domains to a search endpoint and got nothing useful back. Or they sent a set of ICP filters to an enrichment endpoint and wondered why it returned a single contact instead of a list of 4,000.
The contact enrichment API vs lead search API question is not a feature comparison. It is a workflow question. Each endpoint answers a different question, and the question you are asking at a given stage of your outbound pipeline determines which one you should call.
Here is the distinction in one line:
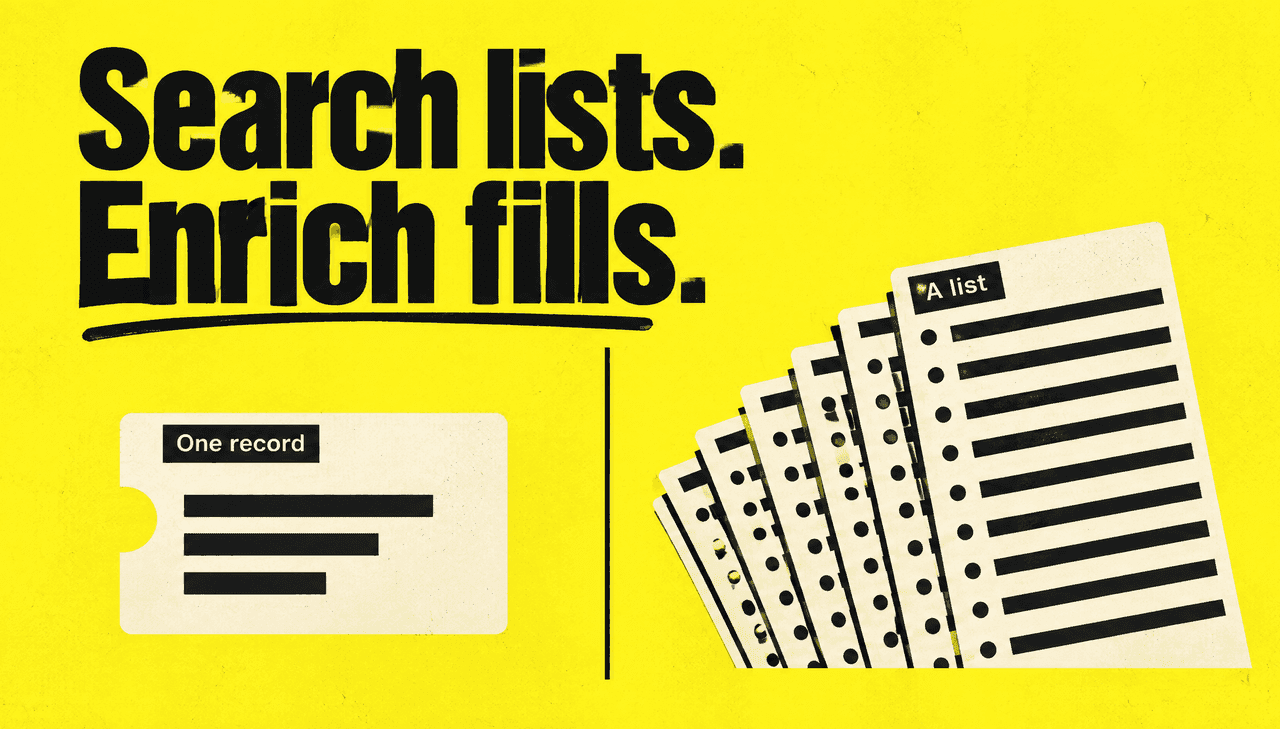
A lead search API takes filters and returns a list. A contact enrichment API takes a known contact or company and returns richer fields about it.
Search is how you find people you do not have. Enrichment is how you complete people you already have. Everything else in this article is a consequence of that split — the input shapes, the output shapes, the credit economics, the failure modes, and the way you chain the two together into a single pipeline.
If you want the parent overview of both endpoints before going deeper, the B2B leads API page covers the full surface area. This article focuses on the decision layer: which endpoint to call, when, and why.
What a contact enrichment API actually does
Enrichment is a lookup operation. It requires an anchor — something that identifies a specific person or company — and it returns additional attributes attached to that anchor.
Typical inputs
- A work email address
- A LinkedIn profile URL
- A name plus a company domain
- A company domain on its own (firmographic enrichment)
- A CRM record ID mapped to one of the above
Typical outputs
- Verified or corrected email address
- Direct dial or mobile phone, where available
- Current job title and normalized seniority level
- Department and function classification
- Company name, domain, employee count, industry, headquarters location
- LinkedIn URL and social handles
The important property of enrichment is that it is deterministic in shape. You send one record, you get one record back. There is no pagination, no result set, no "how many matches are there" question. If the anchor is valid and the record exists in the provider's coverage, you get fields. If it does not, you get a miss.
Where enrichment wins
- CRM cleanup. You have 12,000 records with stale titles and missing phone numbers. Enrichment fixes them in place.
- Inbound lead scoring. A form fill gives you an email and nothing else. Enrichment turns it into a scored, routed, assignable lead with firmographics attached.
- Product-led growth signals. A user signs up with a personal email. Enrichment resolves the company domain so you can route to sales.
- Event and webinar follow-up. You have a badge scan list. Enrichment fills in the gaps before sequencing.
- ABM account completion. You know the target account. Enrichment finds and completes the buying committee inside it.
The common thread: you already have a record, and you need it to be more complete. The contact enrichment API is built for exactly this pattern, including the LinkedIn-URL-first flow that most RevOps teams end up standardizing on.
What a lead search API actually does
Search is a discovery operation. It takes a description of who you want and returns a set of people who match. There is no anchor record — the filters are the input.
Typical inputs
- Job title or role keywords, plus seniority bands
- Industry, sub-industry, or SIC/NAICS classification
- Employee count or revenue range
- Geography — country, region, metro
- Technologies used, funding stage, or growth signals
- Department and function
- Exclusions — competitors, existing customers, suppressed domains
Typical outputs
- A paginated list of matching contacts
- Per-contact fields: name, title, company, domain, location, and often email
- A total match count for the query
- Cursor or page tokens for retrieving the next slice
The important property of search is that it is non-deterministic in size. The same query can return 40 records or 40,000. That is why preview and count endpoints matter so much — you want to know the size of the result set before you start paying to retrieve it.
Where search wins
- Net-new list building. You have an ICP and no list. Search produces the list.
- Market sizing. You want to know how many VP Sales at 50–200 person SaaS companies in North America actually exist in the dataset.
- Territory planning. You need to split a market by geography or segment and assign owners.
- Lookalike expansion. You have 30 great customers. Search finds the 3,000 companies that look like them.
- Recurring pipeline generation. A scheduled job pulls new matches every week. This is the core pattern behind a lead generation API workflow.
The common thread: you do not have the records yet, and you need a set that matches criteria.
Side-by-side comparison
| Dimension | Contact enrichment API | Lead search API |
|---|---|---|
| Input type | Known identifier: email, LinkedIn URL, name + domain | ICP filters: title, industry, size, geo, tech |
| Output type | One enriched record per input record | Paginated list of matching records |
| Result size | Deterministic — 1 in, 1 out | Variable — depends entirely on filter breadth |
| Credit model | Typically charged per successful match or per lookup attempt | Typically charged per record returned, sometimes per page retrieved |
| Ideal workflow stage | Post-capture: CRM cleanup, inbound routing, ABM completion | Pre-capture: net-new prospecting, market sizing, list building |
| Common failure mode | Calling it with no valid anchor, or with a stale anchor that no longer resolves | Calling it with filters so broad the result set is unusable, or so narrow it returns zero |
| Pagination needed | No | Yes — and mishandling it is a top source of wasted credits |
| Best paired with | CRM, product signup flow, inbound forms | Sequencer, export pipeline, territory model |
If you are pulling large result sets from the search side, the mechanics of cursors, page sizes, and dedup across pages are covered in the B2B leads API search filters reference. Getting pagination wrong is the single most expensive mistake in a search-heavy pipeline, and the filter design that drives it deserves the same attention.
Decision framework: which endpoint for which workflow stage
Map your pipeline stage to the endpoint before you write any code. This table is the one most teams should pin somewhere visible.
| Workflow stage | Endpoint | Why |
|---|---|---|
| Net-new prospecting for a new segment | Search | No existing records; you need a list built from criteria |
| Inbound form submission arrives | Enrichment | You have an email; you need firmographics, title, and routing data |
| CRM dedup and record hygiene | Enrichment | Records already exist; you are filling gaps and normalizing |
| ABM target account list refresh | Search, then enrichment | Search finds the committee; enrichment completes missing fields |
| Event or webinar follow-up | Enrichment | You have attendee identities; you need contactable channels |
| Territory or market sizing | Search (count/preview only) | You need volume estimates, not full records |
| Lookalike expansion from closed-won | Search | You are describing a pattern, not looking up known people |
| Product signup with personal email | Enrichment | You have a user; you need the company behind them |
| Weekly recurring pipeline feed | Search, with enrichment on new matches only | Discovery plus completion, with credits spent only where needed |
Notice how many rows say "enrichment" for stages that happen after a record enters your system, and "search" for stages that happen before. That is the whole framework. Search is upstream of your database. Enrichment is downstream of it.
For broader context on how these stages fit into a sales motion, HubSpot's prospecting guide walks through the sequencing logic that search and enrichment ultimately feed.
Three combined workflow patterns
In practice, mature outbound pipelines use both endpoints. Here are the three patterns that show up most often, in order of how common they are.
Pattern 1: Search, then enrich
The default. You run a search query against your ICP, get back a list of contacts with partial data, then enrich the subset that matters — usually the ones you are about to sequence.
- Define ICP filters and preview the match count before spending credits.
- Run the search and page through results, deduping against your suppression list.
- Score or segment the returned records.
- Enrich only the records entering an active sequence.
- Write enriched fields back to the CRM or export destination.
The value of this pattern is that you avoid enriching records you will never contact. If your search returns 8,000 matches and you will only sequence 600 this month, enriching all 8,000 is pure waste.
Pattern 2: Enrich, then search (expand known accounts)
You start from accounts you already care about — closed-won customers, target ABM accounts, or a partner list — and use enrichment to resolve them into a clean set of domains and firmographics. Then you run search queries built from those resolved attributes to find similar accounts or additional buying-committee members.
- Enrich your seed account list to normalize domains, industries, and size bands.
- Cluster the enriched accounts into segments with shared attributes.
- Build search queries from each cluster's dominant attributes.
- Preview counts, then pull the lists that clear your volume threshold.
This is the pattern behind most lookalike and account-expansion programs, and it depends entirely on enrichment output being clean enough to build filters from. Field normalization matters here — the contact enrichment API field mapping guide covers how to keep industry, seniority, and size values consistent enough to feed back into search filters.
Pattern 3: Parallel routing by data confidence
You have a mixed inbound stream: some records arrive with a full set of fields, some arrive with almost nothing. Instead of running everything through the same path, you route by confidence.
- High confidence (work email + company domain + title present): skip enrichment, go straight to scoring and routing.
- Medium confidence (work email only): enrich to fill title, seniority, and firmographics.
- Low confidence (personal email, no domain): enrich to resolve the company, then decide whether to route to sales or to a nurture track.
- No match after enrichment: route to a manual review queue rather than burning further credits on retries.
This pattern is the most credit-efficient of the three because it never pays for data you already have. It does require you to define confidence tiers explicitly, which is a one-time design decision that pays off indefinitely.
Credit economics and budget planning
Credits are the operational constraint that turns an architectural decision into a budget decision. The two endpoints consume credits differently, and mixing them without a plan is how teams end up with a mid-month overage.
| Cost driver | Enrichment endpoint | Search endpoint |
|---|---|---|
| What you pay for | Lookups, often billed on successful match | Records returned, sometimes per page retrieved |
| Predictability | High — cost scales linearly with input volume | Low — cost scales with filter breadth, which you control but can misjudge |
| Biggest waste risk | Enriching records you never contact | Pulling oversized result sets, or re-pulling pages you already have |
| Mitigation | Enrich at the point of sequencing, not at the point of capture | Preview counts first, cap page size, dedup across pages |
Two habits keep credit spend under control regardless of which endpoint dominates your pipeline.
First, preview before you pull. A count or preview call tells you how large a result set is before you commit to retrieving it. If a filter combination returns 90,000 records and your monthly budget supports 5,000, you need to tighten the filters — not discover the problem after the fact. The preview leads endpoint exists for exactly this step: validate a segment's size and coverage before any credits are spent on retrieval.
Second, enrich late. Enrichment is most valuable immediately before a record enters an active sequence or gets written to a system that depends on the enriched fields. Enriching at capture time means you pay for records that may sit untouched for months and go stale before anyone contacts them.
Workflow design checklist
Before you wire either endpoint into production, walk this list. It is short, and every item on it has cost a team real credits at some point.
- Define the ICP before writing filters. Vague criteria produce vague result sets and unpredictable credit spend.
- Preview counts before running a full search. Validate that the segment exists at a useful size before retrieving it.
- Enrich only records with a valid anchor. No email, no LinkedIn URL, no name-plus-domain means no enrichment call.
- Dedup before export, not after. Duplicate records in a search result set are duplicate credits.
- Handle pagination explicitly. Track cursors, cap page sizes, and stop when the result set is exhausted rather than looping blindly.
- Log credit spend per stage. Attribute cost to search, enrichment, and retries separately so you can see which stage is actually expensive.
- Set a retry policy. One retry on a transient failure is reasonable. Three retries on a record that does not exist is a budget leak.
- Define a no-match path. Decide in advance what happens to records that fail enrichment, so they do not silently re-enter the queue.
Common mistakes when mixing the two endpoints
Calling enrichment without a known identifier. Enrichment is not a search engine. If you send a job title and a city, you are asking the wrong endpoint for the wrong thing. Send an anchor.
Calling search without meaningful filters. A search with one broad filter returns a result set too large to use and too expensive to retrieve. Narrow with two or three intersecting criteria before you pull.
Double-charging on dedup. If you pull the same segment weekly and do not dedup against previously retrieved records, you pay for the same contacts repeatedly. Maintain a suppression set of already-retrieved identifiers.
Ignoring pagination limits. Search endpoints cap how much you can retrieve per call. Teams that assume a single call returns everything end up with truncated lists and no error to tell them so.
Enriching before segmenting. If you enrich an entire raw list and then narrow it down, you paid for records you discarded. Segment first, enrich second.
Treating enrichment output as final. Enrichment returns the best available value at the time of the call. Titles change, people move. Build a refresh cadence rather than assuming a one-time enrichment is permanent.
Implementation notes for RevOps and product teams
Once the endpoint decision is made, the implementation details determine whether the pipeline is maintainable.
Field mapping and normalization
Enrichment responses need to be mapped into your CRM's schema, and the mapping has to handle missing values, casing differences, and title variations. Normalizing seniority into a fixed set of bands — rather than storing raw title strings — is what makes downstream filtering and routing reliable. This is the same normalization discipline that makes enrichment field mapping work across multiple data sources.
Sync vs async calls
Single-record enrichment is usually fine as a synchronous call inside a form handler or a webhook. Bulk enrichment and large search retrievals should be asynchronous jobs with a queue, so a slow response does not block a user-facing request.
Rate limits and batching
Respect the documented rate limits and batch where the API supports it. Batching reduces request overhead but increases the blast radius of a failed call — so batch in sizes you can retry cheaply.
CRM write-back logic
Decide which fields enrichment is allowed to overwrite. A common rule: enrichment can fill empty fields freely, but can only overwrite populated fields when the existing value is older than a defined staleness threshold. This prevents a fresh manual update from being clobbered by an automated refresh.
Lead lifecycle framing
Search and enrichment sit at different points in the lead lifecycle, and the lifecycle model should reflect that. Salesforce's Lead Management implementation guide is a useful reference for structuring the stages that enrichment and search feed into, particularly around when a record becomes actionable versus merely captured. For the broader pipeline view, Salesforce's B2B lead generation guide maps those stages onto a full funnel.
Closing: choosing the right endpoint per workflow stage
The rule is simple enough to remember without a diagram:
- Search when you need a list. You have criteria and no records.
- Enrich when you already have a contact. You have a record and need it complete.
Everything else — credit budgeting, pagination handling, dedup strategy, field mapping — is downstream of getting that first decision right. Teams that route correctly spend less, ship faster, and stop blaming the data for problems that were actually architectural.
If your pipeline is mostly post-capture — CRM hygiene, inbound routing, ABM completion, product-led company resolution — start with the contact enrichment API and design your confidence tiers around it. If you are building net-new pipeline on a schedule, pair it with the search side and let enrichment run only on the records that clear your sequencing threshold. That combination is what a durable lead generation API workflow actually looks like in production.
Pick the endpoint that matches the stage. Then measure credits per stage, not credits per month — that is the number that tells you whether the architecture is working.