Dievio
Key points
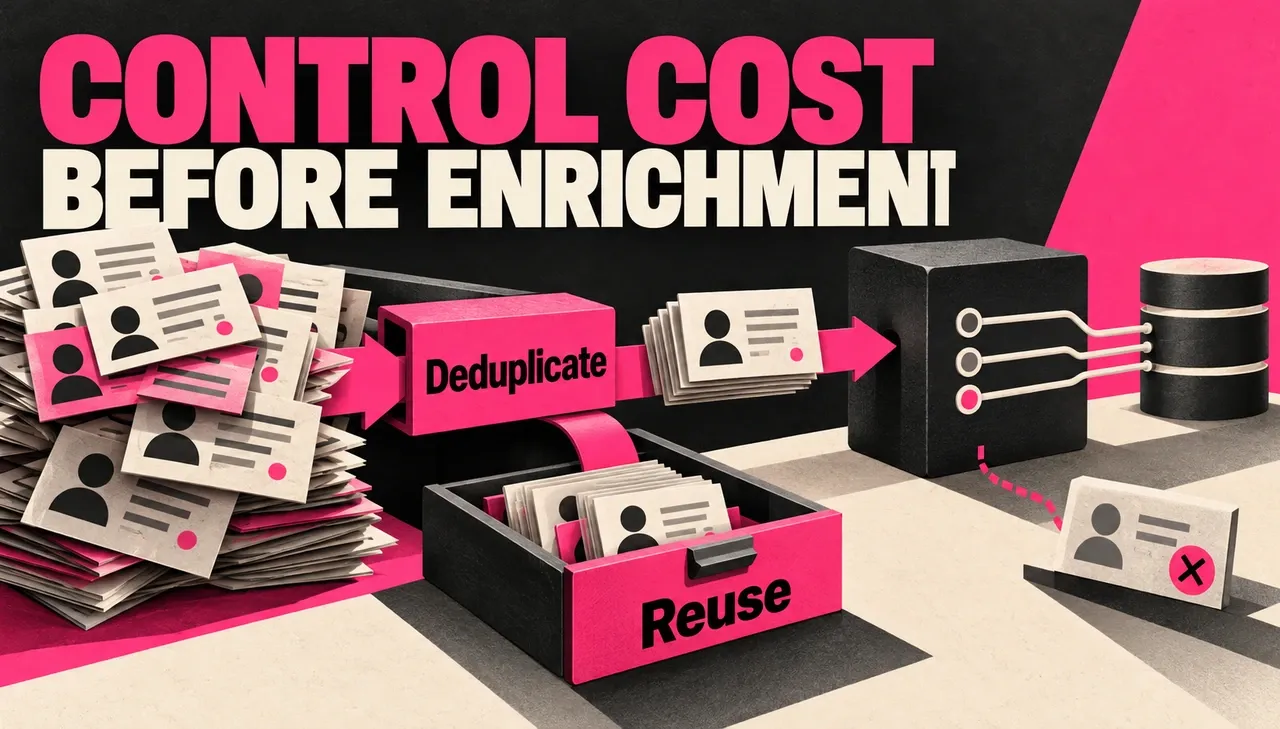
- Deduplicate logical requests before enrichment and checkpoint successful work.
- Confirm billing rules before assuming fewer fields mean lower costs.
- Measure cost per usable contact under consistent acceptance criteria.
Contact enrichment API costs depend on which records you send, what your provider bills for, and how you handle repeats and failures. Start by removing unnecessary work before tuning request volume. A smaller response payload alone does not establish a lower bill.
The three workflows below are illustrative designs for a sales team, a RevOps team and an agency. They are not customer case studies or measured savings claims. Adapt them to your provider's documented endpoints, billing events and data retention rules.
Measure useful output before changing the pipeline
Define a usable result for the campaign. For an email campaign, that might mean a contact at a matching company, in an approved role, with an available work address that passes your separate validation process. A returned object is not automatically a usable lead.
| Measure | Calculation | What it reveals |
|---|---|---|
| Cost per usable contact | Total relevant enrichment spend divided by unique contacts meeting the acceptance rules | Whether lower API spend actually improves efficiency |
| Duplicate request rate | Repeat logical lookups divided by all attempted lookups | Work that a suitable cache or deduplication step might avoid |
| Usable match rate | Unique accepted results divided by unique contacts submitted | How well sourcing and acceptance rules fit the workflow |
| Failure recovery rate | Recoverable failed jobs completed without duplicate downstream records divided by recoverable failed jobs | Whether retries preserve correctness |
Keep the denominator consistent between periods. Changes in audience, required fields or provider prices can explain a cost difference even when the integration code stays the same.
Example 1: pre-filter and deduplicate an outbound batch
Starting problem: a sales team combines several prospect files and submits every row for enrichment. The same person may appear under multiple imports, and some companies fall outside the agreed ICP.
- Normalize identifiers. Standardize supported profile URLs and domains. Preserve original values for investigation. Do not collapse two people because their names happen to match.
- Apply campaign exclusions. Check customer exclusions, role relevance and suppression before enrichment. Route ambiguous records for review rather than silently accepting them.
- Deduplicate the logical request. Use the stable identifier, requested operation and freshness requirements as part of the key. A phone lookup and an email lookup need not be equivalent requests.
- Check the existing result. Reuse it only when its age, permission and fields satisfy the current task. A cache entry is not evidence that an email remains deliverable.
- Process bounded batches. Choose sizes within documented limits and checkpoint completed work. A pagination page size is not necessarily an enrichment upload limit.
Illustrative calculation: if a file has 1,000 rows and 150 are exact repeat requests, deduplication leaves 850 logical requests before any other filtering. That is a reduction in requests, not a guaranteed reduction in billed spend: the provider may bill attempts, matches, returned records or another event.
Compare cost per usable contact and the number of accepted contacts after the change. For extraction details, see the pagination workflow.

Example 2: enrich conditionally before a CRM update
Starting problem: a RevOps workflow re-enriches every contact after every form update, then overwrites reviewed CRM fields with incomplete provider data.
Define the destination schema first. For each field, record whether it is required, which source is authoritative and what to do when enrichment returns no value. Then trigger enrichment only when the record has an approved need, such as a missing required attribute or an expired review date.
- Keep source timestamps and provenance alongside values where the system supports them.
- Do not replace a manually confirmed company or role with an empty or lower-confidence result.
- Use an upsert strategy with an explicit identity rule to avoid creating a second CRM contact during retries.
- Distinguish request failure, no match, missing field and validation failure in the job log.
- Keep sensitive fields out of routine application logs.
Field selection can reduce payload size and mapping work when the API supports it. It reduces monetary cost only if the provider's billing model charges differently for the selected operation or fields. Confirm that relationship before forecasting savings. Use the field mapping guide to define the transformation.
 Dievio
Your workflow. Powered by Dievio.
Bring B2B contact search and LinkedIn enrichment into the tools you already use.
Explore Dievio APISearch contacts · Enrich profiles · Export results
{
  "job_titles": ["Founder"],
  "max_results": 10
}Example 3: control enrichment by agency delivery scope
Starting problem: an agency gives every client the same enrichment depth, even though one campaign needs email contacts and another has an approved phone outreach process. Internal effort and provider spend are difficult to attribute.
Create a delivery specification for each client before requesting data. Include the audience, approved fields, validation rules, intended channels, delivery format and review deadline. Keep client identifiers on jobs and output records so costs and exclusions do not cross accounts.
| Delivery scope | Request decision | Acceptance check |
|---|---|---|
| Email campaign input | Request the necessary contact data where available | Role fit, company match, suppression and separate email validation |
| Phone campaign input | Request phones only when the provider supports the operation and the campaign permits calling | Number availability, attribution and applicable calling preferences |
| Research shortlist | Defer enrichment until account or persona fit is confirmed | Research evidence and approval for the next stage |
Set a budget guard for each client and define what happens when it is reached. Pause or request a scope decision instead of silently lowering quality. Verify the provider's permitted use and redistribution terms before packaging data for resale or white-label delivery.
Recover failures without creating extra work
Assign a stable job ID and record successful completion before advancing the checkpoint. Retry only recoverable failures according to the provider's instructions; use backoff and any supported retry guidance. Authentication errors, invalid input and no-match results need different handling from transient server failures.
A timeout can leave the outcome uncertain. Check provider job status or your recorded result before repeating an operation that may be billable. If idempotency is documented, use it as specified; do not assume every endpoint supports an idempotency key. See the error handling and retry design for the broader pipeline.
Validate savings against an unchanged acceptance rule
Run the revised workflow on a bounded, comparable cohort. Record requests, billed events, usable contacts, duplicates, manual review time and downstream failures. Explain any audience or price changes. Report the observed outcome with its date and sample rather than importing an industry savings percentage.
For Dievio integrations, consult the API entry point and current documentation for implemented capabilities. Count previews, lead retrieval, saved-list export and API credit purchases have distinct purposes; use the relevant billing rules for the operation you actually run. This article's example architecture is not a promise of native webhooks, CRM connectors, field-specific billing or automatic email verification.